Kód: 37111849
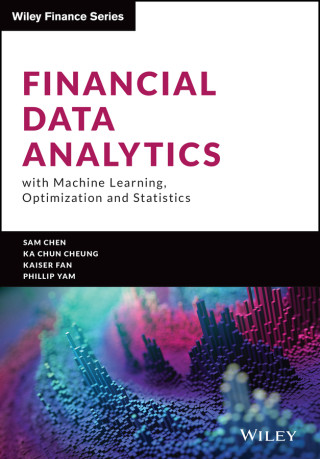
Financial Data Analytics with Machine Learning, Op timization and Statistics
Autor Yongzhao Chen, Ka Chun Cheung, Phillip Yam
An essential introduction to data analytics and Machine Learning techniques in the business sector In Financial Data Analytics with Machine Learning, Optimization and Statistics, a team consisting of a distinguished applied mathem ... celý popis


- Jazyk:
 Angličtina
- Vazba: Pevná
- Počet stran: 512
Nakladatelství: John Wiley & Sons Inc, 2023
- Více informací o knize

1628 Kč

Skladem u dodavatele v malém množství
Odesíláme za 12-17 dnů
Potřebujete více kusů?Máte-li zájem o více kusů, prověřte, prosím, nejprve dostupnost titulu na naši zákaznické podpoře.
Přidat mezi přání
Mohlo by se vám také líbit
-

The Flavor Bible : The Essential Guide to Culinary Creativity, Based on the Wisdom of America's Most Imaginative Chefs
790 Kč -
Nocticadia
227 Kč -
The Risk
227 Kč -
Tomie: Complete Deluxe Edition
588 Kč -
Chainsaw Man, Vol. 2
221 Kč -
Wind and Truth
596 Kč -
Own It! Level 2 Workbook with eBook
319 Kč -
Ballad of Sword and Wine: Qiang Jin Jiu (Novel) Vol. 3
325 Kč -
Blood of Dragons
248 Kč -
Perfume
292 Kč -
Jade War
235 Kč -
Outer Banks: Lights Out
225 Kč -
Radical Acceptance
350 Kč -
Old Style Lenormand
272 Kč -
Classroom of the Elite (Light Novel) Vol. 7.5
258 Kč -
Arabs
445 Kč -
WKW: The Cinema of Wong Kar Wai
1108 Kč -
Beaded Flowers, Bouquets, & Garlands
219 Kč -
The Selection 1-5 Box Set
991 Kč -
Tattoo Machine Builder: The Bulldog Frame
485 Kč -
The Little Prince
150 Kč -
Three Hundred Years of Longing: Bu Jian Shang Xian San Bai Nian 1
325 Kč -
The Encyclopedia of Ugly Fashion
457 Kč -
Calculus
857 Kč -
Legend Of Korra: Ruins Of The Empire Omnibus
514 Kč -
KOREA
408 Kč -
The Rising of the Shield Hero, Volume 1
241 Kč -
David Busch's Sony Alpha A6700/Ilce-6700 Guide to Digital Photography
818 Kč -
Classroom of the Elite: Year 2 (Light Novel) Vol. 10
361 Kč -
Girls' Last Tour, Vol. 4
394 Kč -
Under Saturn's Shadow
358 Kč -
The Road to Unfreedom
276 Kč -
Knitting Fresh Brioche
412 Kč -
Stylish Life: Skiing
662 Kč -
Emotional Intelligence Habits
598 Kč -
Dr. STONE, Vol. 8
179 Kč -
The Culture Code
245 Kč -
Indestructibles: Baby, See the Colors!
116 Kč -
HTML & CSS: Design and Build Websites
495 Kč -
Practical Ayurveda
358 Kč -
Roman Soldier Vs Dacian Warrior
357 Kč -
Wives and Daughters
118 Kč -
General Relativity for the Gifted Amateur
1128 Kč -
Thirty Years War
616 Kč -
Mom, I Want to Hear Your Story
400 Kč -
Abductive Reasoning
744 Kč -
Official Cambridge Guide to IELTS Student's Book with Answers with DVD-ROM
2071 Kč -
Microsoft Excel Data Analysis and Business Modeling (Office 2021 and Microsoft 365)
956 Kč -
Eastern Heroes Bruce Lee Way of the dragon bumper issue
754 Kč -
Stochastic Calculus for Finance II
1384 Kč -
Four Chapters on Freedom
693 Kč -
Financial Planning & Analysis and Performance Management
1143 Kč -
Financial Controller
590 Kč -
First Love
146 Kč -
Grammar 1 Workbook 1
104 Kč -
A Mind at Home with Itself: How Asking Four Questions Can Free Your Mind, Open Your Heart, and Turn Your World Around
332 Kč -
Python for Algorithmic Trading
1268 Kč -
Then Came You
196 Kč -
Advanced Mathematical Techniques: for Scientists and Engineers, second edition
811 Kč -
Common Sense, The Rights Of Man And Other Essential Writings
174 Kč -
Business Data Science: Combining Machine Learning and Economics to Optimize, Automate, and Accelerate Business Decisions
752 Kč -
Crystals and Numerology
308 Kč -
Financial Analysis: Fourth Edition
673 Kč -
Chief Data Officer's Playbook
873 Kč -
Artificial Intelligence in Finance
1423 Kč -
Christmas Carol
205 Kč -
Holy Bible
557 Kč -
Forbes Greatest Business Stories of All Time Inspiring Tales of Entrepreneurs Who Changed the Way We Live & Do Business (Paper)
459 Kč -
Krav Maga Combatives
474 Kč -
Mastering Microsoft Power BI - Second Edition
1064 Kč -
Peppa Pig: On a Boat - Ladybird Readers Level 1
144 Kč -
Wisdom of Mike Mentzer
568 Kč -
Jolly Stories
632 Kč -
Urban Planning for Dummies
450 Kč -
Topsy and Tim: Have Their Eyes Tested
138 Kč -
Four to Score
210 Kč -
The National Gallery. Paintings, People, Portraits
3763 Kč -
The Sadhana of Mahamudra
495 Kč -
Data Strategy
795 Kč -
Civilizing Process 2e
924 Kč -
EU Administrative Law
2617 Kč -
Excel Sales Forecasting For Dummies, 2e
558 Kč -
Excel Data Analysis For Dummies, 5th Edition
725 Kč -
Fraud Analytics Using Descriptive, Predictive, and Social Network Techniques - A Guide to Data Science for Fraud Detection
892 Kč -
Controlling Concept, The: Cornerstone Of Performance Management
2388 Kč -
Master Data Management in Practice
1275 Kč -
Analysis of Financial Data
1434 Kč -
Financial Forecasting, Analysis, and Modelling
1707 Kč -
Coping With Institutional Order Flow
4115 Kč -
Introduction to Modern Cosmology
1232 Kč -
Fraud Analytics - Strategies and Methods for Detection and Prevention
858 Kč
Darujte tuto knihu ještě dnes
- Objednejte knihu a zvolte Zaslat jako dárek.
- Obratem obdržíte darovací poukaz na knihu, který můžete ihned předat obdarovanému.
- Knihu zašleme na adresu obdarovaného, o nic se nestaráte.
Více informací o knize Financial Data Analytics with Machine Learning, Op timization and Statistics
Nákupem získáte 163 bodů
 Anotace knihy

An essential introduction to data analytics and Machine Learning techniques in the business sector
In Financial Data Analytics with Machine Learning, Optimization and Statistics, a team consisting of a distinguished applied mathematician and statistician, experienced actuarial professionals and working data analysts delivers an expertly balanced combination of traditional financial statistics, effective machine learning tools, and mathematics. The book focuses on contemporary techniques used for data analytics in the financial sector and the insurance industry with an emphasis on mathematical understanding and statistical principles and connects them with common and practical financial problems. Each chapter is equipped with derivations and proofs--especially of key results--and includes several realistic examples which stem from common financial contexts. The computer algorithms in the book are implemented using Python and R, two of the most widely used programming languages for applied science and in academia and industry, so that readers can implement the relevant models and use the programs themselves.
The book begins with a brief introduction to basic sampling theory and the fundamentals of simulation techniques, followed by a comparison between R and Python. It then discusses statistical diagnosis for financial security data and introduces some common tools in financial forensics such as Benford's Law, Zipf's Law, and anomaly detection. The statistical estimation and Expectation-Maximization (EM) & Majorization-Minimization (MM) algorithms are also covered. The book next focuses on univariate and multivariate dynamic volatility and correlation forecasting, and emphasis is placed on the celebrated Kelly's formula, followed by a brief introduction to quantitative risk management and dependence modelling for extremal events. A practical topic on numerical finance for traditional option pricing and Greek computations immediately follows as well as other important topics in financial data-driven aspects, such as Principal Component Analysis (PCA) and recommender systems with their applications, as well as advanced regression learners such as kernel regression and logistic regression, with discussions on model assessment methods such as simple Receiver Operating Characteristic (ROC) curves and Area Under Curve (AUC) for typical classification problems.
The book then moves on to other commonly used machine learning tools like linear classifiers such as perceptrons and their generalization, the multilayered counterpart (MLP), Support Vector Machines (SVM), as well as Classification and Regression Trees (CART) and Random Forests. Subsequent chapters focus on linear Bayesian learning, including well-received credibility theory in actuarial science and functional kernel regression, and non-linear Bayesian learning, such as the Naïve Bayes classifier and the Comonotone-Independence Bayesian Classifier (CIBer) recently independently developed by the authors and used successfully in InsurTech.
After an in-depth discussion on cluster analyses such as K-means clustering and its inversion, the K-nearest neighbor (KNN) method, the book concludes by introducing some useful deep neural networks for FinTech, like the potential use of the Long-Short Term Memory model (LSTM) for stock price prediction.
This book can help readers become well-equipped with the following skills:
* To evaluate financial and insurance data quality, and use the distilled knowledge obtained from the data after applying data analytic tools to make timely financial decisions
* To apply effective data dimension reduction tools to enhance supervised learning
* To describe and select suitable data analytic tools as introduced above for a given dataset depending upon classification or regression prediction purpose
The book covers the competencies tested by several professional examinatio
Parametry knihy
Zařazení knihy Knihy v angličtině Mathematics & science Mathematics
1628 Kč
- Plný název: Financial Data Analytics with Machine Learning, Op timization and Statistics
- Autor: Yongzhao Chen, Ka Chun Cheung, Phillip Yam
- Jazyk: Angličtina
- Vazba: Pevná
- Počet stran: 512
- EAN: 9781119863373
- ISBN: 1119863376
- ID: 37111849
- Nakladatelství: John Wiley & Sons Inc
- Hmotnost: 1055 g
- Rozměry: 244 × 170 mm
- Datum vydání: 12. October 2023
Oblíbené z jiného soudku
-
Mathematics Analysis and Approaches for the IB Diploma Higher Level
2508 Kč -
Pearson Edexcel International A Level Mathematics Pure 2 Mathematics Student Book
864 Kč -
Basic Mathematics
1154 Kč -
No Bullshit Guide to Math and Physics
537 Kč -
Problems And Solutions In Mathematics (2nd Edition)
2027 Kč -
Trachtenberg Speed System of Basic Mathematics
291 Kč -
Euclidean Geometry and Transformations
334 Kč -
5 Steps to a 5: 500 AP Statistics Questions to Know by Test Day, Third Edition
292 Kč -
Pearson Edexcel GCSE (9-1) Mathematics Higher Student Book 2
583 Kč -
Theory of Graphs
274 Kč -
Riemann's Zeta Function
411 Kč -
Advanced Trigonometry
358 Kč -
International Mathematical Olympiad Volume 2
486 Kč -
Pearson Edexcel GCSE (9-1) Mathematics Higher Student Book 1
578 Kč -
Mathematics Applications and Interpretation for the IB Diploma Standard Level
2648 Kč -
Introduction to Tensor Calculus, Relativity and Cosmology
308 Kč -
Cambridge International AS & A Level Mathematics Pure Mathematics 1 Student's Book
704 Kč -

Colossal Book of Mathematics
801 Kč -
First Step To Mathematical Olympiad Problems, A
835 Kč -
Riemann Zeta-Function: Theory A
489 Kč -
Challenging Mathematical Problems with Elementary Solutions, Vol. II
256 Kč -
Challenging Mathematical Problems with Elementary Solutions, Vol. I
256 Kč -
Method of Coordinates
162 Kč -
Mathematics: A Very Short Introduction
225 Kč -
Mathematics
1034 Kč -
Matrices and Transformations
178 Kč -
Fractals
196 Kč -
Mathematics for Economists
1717 Kč -
Counterexamples in Analysis
389 Kč -
Topology (Classic Version)
2693 Kč -
Practical Algebra: A Self-Teaching Guide, Third Ed ition
412 Kč -
Simply Maths
276 Kč -
Mathematical Universe - An Alphabetical Journey Through the Great Proofs, Problems & Personalities (Paper)
428 Kč -
Introducing Mathematics
250 Kč -
Der Mathematik-Kalender Tagesabreißkalender 2027 - Nachts teile ich heimlich durch Null
324 Kč -
Mathematical Conversations
941 Kč -
Topics in Number Theory Vol 1 and 2
429 Kč -
Short-cut Mathematics
200 Kč -
All the Math You'll Ever Need: A Self-Teaching Gui de, Third Edition
419 Kč -
Calculus For The Practical Man
774 Kč -
Love and Math
334 Kč -
Solving Mathematical Problems
919 Kč -
Mathematics for the Non-mathematician
567 Kč -
Stanford Mathematics Problem Book
234 Kč -
General Topology
412 Kč -
Introduction to Combinatorial Analysis
302 Kč -
Elementary Mathmatics from an Advan
256 Kč -
Math Art
614 Kč -
Principia
454 Kč
Osobní odběr Praha, Brno a 47960 dalších
Copyright ©2008-26 nejlevnejsi-knihy.cz Všechna práva vyhrazenaSoukromíCookies

 Vrácení do měsíce
 571 999 099 (8-15.30h)
