Kód: 54515559
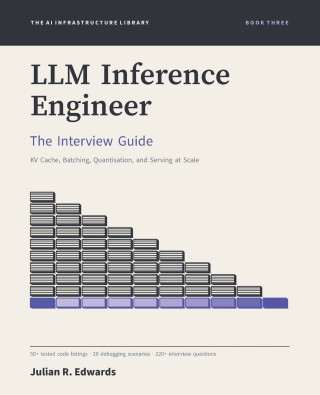
LLM Inference Engineer
Autor Julian R. Edwards
Prepare for the interview that asks how many users your GPUs can serve.LLM inference interviews are unlike other engineering interviews. You may be asked how much memory a model needs to serve a hundred users at 8,000 tokens of co ... celý popis


- Jazyk:
 Angličtina
- Vazba: Brožovaná
- Počet stran: 202
Nakladatelství: Independently published, 2026
- Více informací o knize


Mohlo by se vám také líbit
-
Threshing Day (Limited Deluxe Edition)
441 Kč -
Cozy Countdown: An Advent Coloring Book Bundle
514 Kč -
Court of Thorns and Roses 6
348 Kč -
Murdoku
342 Kč -
White Nights
82 Kč -
Trust Fall
227 Kč -

A Conspiracy of Charming Monsters
419 Kč -
I'll Believe in Anything. The Making of Heated Rivalry Season 1
460 Kč -
The Mirror of Infinite Endings
434 Kč -

A Conspiracy of Charming Monsters
276 Kč -
Once Upon a Broken Heart Collector's Edition
630 Kč -
The Long-Lived King: An Original The Owl House Graphic Novel
385 Kč -

Chainsaw Man, Vol. 22
230 Kč -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 9
438 Kč -
Berserk Deluxe Volume 1
899 Kč -
Protocols
428 Kč -
Murdoku Volume 2: Back in Time
293 Kč -
The End of Everything
292 Kč -
21 Days of Fear
406 Kč -
Threshing Day (Wing and Claw Collection)
453 Kč -
How to Win at Chess, Next Level
506 Kč
Darujte tuto knihu ještě dnes
- Objednejte knihu a zvolte Zaslat jako dárek.
- Obratem obdržíte darovací poukaz na knihu, který můžete ihned předat obdarovanému.
- Knihu zašleme na adresu obdarovaného, o nic se nestaráte.
Informovat o naskladnění knihy
Zadejte do formuláře e-mailovou adresu a jakmile knihu naskladníme, zašleme vám o tom zprávu. Pohlídáme vše za vás.
Více informací o knize LLM Inference Engineer
Nákupem získáte 55 bodů
 Anotace knihy

Prepare for the interview that asks how many users your GPUs can serve.
LLM inference interviews are unlike other engineering interviews. You may be asked how much memory a model needs to serve a hundred users at 8,000 tokens of context, why time to first token tripled when a customer started sending long documents, or to write the part of a serving engine that decides which requests run next and what happens when memory runs out. Each question has an answer you can reach with a minute of arithmetic and a precise understanding of a few mechanisms.
This book teaches both. It builds a working miniature inference engine, one mechanism per chapter, and derives every capacity, latency and cost figure from first principles, so you can reason about any model on any hardware.
Inside you'll find:
- The arithmetic of inference: prefill and decode, hardware bounds, TTFT, TPOT, goodput and Little's law, with worked estimation drills
- The engine, in working code: the KV cache, paged memory with prefix caching and copy-on-write, continuous batching with chunked prefill and preemption, sampling and structured output, speculative decoding and quantisation
- Scaling out: tensor, pipeline and expert parallelism, mixture-of-experts models, disaggregated prefill and decode, and long context
- The serving system: routing, rate limiting, autoscaling, multi-LoRA serving, capacity planning, cost per token, benchmarking and observability
- Interview practice: the coding round with tested solutions, 20 debugging scenarios, 8 design questions, rubrics of strong signals and red flags, and over 220 questions with answers
- Reference appendices: GPU and model tables, engine settings, a glossary and further reading
Code you can trust. Every listing comes from a small engine that runs on an ordinary laptop, and its tests check that batching, chunking, preemption and prefix caching never change a single output token compared with the simplest possible generation loop. Performance figures are bounds computed from published specifications, with the arithmetic shown, never invented benchmarks.
Who it's for: engineers preparing for LLM inference, model serving and inference-optimisation roles, including backend and infrastructure engineers moving into AI, ML engineers moving towards serving, and GPU engineers moving up the stack. You should be able to read Python. Book Three of The AI Infrastructure Library; it can be read on its own.
Parametry knihy
545 Kč
- Plný název: LLM Inference Engineer
- Podnázev: The Interview Guide: KV Cache, Batching, Quantisation, and Serving at Scale - 50+ Tested Code Listings, 20 Debugging Scenarios, and 220+ Questions with Answers
- Autor: Julian R. Edwards
- Jazyk: Angličtina
- Vazba: Brožovaná
- Počet stran: 202
- EAN: 9798141641879
- ID: 54515559
- Nakladatelství: Independently published
- Hmotnost: 358 g
- Rozměry: 235 × 191 × 11 mm
- Datum vydání: 10. November 2026
Osobní odběr Praha, Brno a 48478 dalších
Copyright ©2008-26 nejlevnejsi-knihy.cz Všechna práva vyhrazenaSoukromíCookies

 Vrácení do měsíce
 571 999 099 (8-15.30h)
