Kód: 05285152
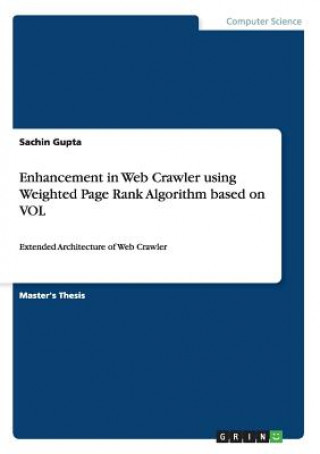
Enhancement in Web Crawler using Weighted Page Rank Algorithm based on VOL
Autor Sachin Gupta
Master's Thesis from the year 2014 in the subject Computer Science - Miscellaneous, , course: M.Tech, language: English, comment: Excellent , abstract: As the World Wide Web is growing rapidly day by day, the number of web pages i ... celý popis


- Jazyk:
 Angličtina
- Vazba: Brožovaná
- Počet stran: 98
Nakladatelství: Grin Publishing, 2014
- Více informací o knize


Mohlo by se vám také líbit
-

The Homeopath in Your Hand
754 Kč -

Spelling and Vocabulary Workbook (Ages 5-6)
173 Kč -

Outlines of Pyrrhonism
265 Kč -

Русский язык. 3 класс. Учебник. В двух частях (Школа России)
1301 Kč -

Torchon Lace Workbook
525 Kč -

Competitive Advantage of Nations
1708 Kč -

Die Bar-Piano Schule. Bd.1
440 Kč -

Declutter Your Mind
475 Kč -

The Poor Artist: Or Seven Eye-Sights And One Object (1850)
663 Kč -

A Birthday Reunion
196 Kč -

Nature et fonctions cérébrales selon Aristote
4524 Kč -

Soho Square
373 Kč -

entburokratisierte Pflegedokumentation
713 Kč -
Trumpet Exam Pieces 2010 CD, ABRSM Grade 2
512 Kč -

Migraciones y cultura de paz : educando y comunicando solidaridad
615 Kč -
Beginning Microsoft Word 2010
608 Kč -

Donjon - Hoher Septentrion
330 Kč -
Race and the Third Reich: Linguistics, Racial Anthropology and Genetics in the Dialectic of Volk
1782 Kč -
Concert Song Companion
1181 Kč -

Qualité de vie après un accident vasculaire cérébral
1115 Kč -
Iran-U.S. Claims Tribunal Reports volume 25
2821 Kč -

Higher Education, Fiscal Administration, and Budgeting
1826 Kč -

Missiles Scut
135 Kč -

My Last Poems
401 Kč -

Handbuch Der Verfassung Und Verwaltung in Preussen Und Dem Deutschen Reich
1214 Kč -

All the Ways to Go
308 Kč -
Portal Hypertension in the 21st Century
4115 Kč -

Indianas Seis Canciones
237 Kč
Darujte tuto knihu ještě dnes
- Objednejte knihu a zvolte Zaslat jako dárek.
- Obratem obdržíte darovací poukaz na knihu, který můžete ihned předat obdarovanému.
- Knihu zašleme na adresu obdarovaného, o nic se nestaráte.
Více informací o knize Enhancement in Web Crawler using Weighted Page Rank Algorithm based on VOL
Nákupem získáte 98 bodů
 Anotace knihy

Master's Thesis from the year 2014 in the subject Computer Science - Miscellaneous, , course: M.Tech, language: English, comment: Excellent , abstract: As the World Wide Web is growing rapidly day by day, the number of web pages is increasing into millions and trillions around the world. To make searching much easier for users, search engines came into existence. Web search engines are used to find specific information on the WWW. Without search engines, it would be almost impossible for us to locate anything on the Web unless or until we know a specific URL address. Every search engine maintains a central repository or databases of HTML documents in indexed form. Whenever a user query comes, searching is performed within that database of indexed web pages. The size of repository of every search engine can t accommodate each and every page available on the WWW. So it is desired that only the most relevant and important pages are stored in the database to increase the efficiency of search engines. This database of HTML documents is maintained by special software called Crawler . A Crawler is software that traverses the web and downloads web pages. Broad search engines as well as many more specialized search tools rely on web crawlers to acquire large collections of pages for indexing and analysis. Since the Web is a distributed, dynamic and rapidly growing information resource, a crawler cannot download all pages. It is almost impossible for crawlers to crawl the whole web pages from World Wide Web. Crawlers crawls only fraction of web pages from World Wide Web. So a crawler should observe that the fraction of pages crawled must be most relevant and the most important ones, not just random pages. In our Work, we propose an extended architecture of web crawler of search engine, to crawl only relevant and important pages from WWW, which will lead to reduced sever overheads. With our proposed architecture we will also be optimizing the crawled data by removing least or never browsed pages data. The crawler needs a very large memory space of database for storing page content etc, by not storing irrelevant and unimportant pages and removing never accessed pages, we will be saving a lot of memory space that will eventually speed up the searches (queries) from the database. In our approach, we propose to use Weighted page Rank based on visits of links algorithm to sort the search results, which will reduce the search space for users, by providing mostly visited pages links on the top of search results list.
Parametry knihy
Zařazení knihy Knihy v angličtině Computing & information technology Information technology: general issues
975 Kč
- Plný název: Enhancement in Web Crawler using Weighted Page Rank Algorithm based on VOL
- Podnázev: Extended Architecture of Web Crawler
- Autor: Sachin Gupta
- Jazyk: Angličtina
- Vazba: Brožovaná
- Počet stran: 98
- EAN: 9783656700043
- ISBN: 3656700044
- ID: 05285152
- Nakladatelství: Grin Publishing
- Hmotnost: 136 g
- Rozměry: 210 × 148 × 6 mm
- Datum vydání: 25. July 2014
Oblíbené z jiného soudku
-

Streaming Systems
1492 Kč -
Bpmn 2.0
410 Kč -
Cult of the Dead Cow
408 Kč -
Using SAP S/4HANA
489 Kč -

World Wide Waste
485 Kč -
Playful Production Process
1374 Kč -

Let Over Lambda
903 Kč -

Real Time Visual Effects for the Technical Artist
1705 Kč -

Big Data, Big Dupe
246 Kč -
Technology Made Simple for the Technical Recruiter, Second Edition
290 Kč -
Elements of Computing Systems
1305 Kč -
Machine Learning For Dummies, 2nd Edition
608 Kč -
Founders at Work
490 Kč -
Scrumban - Essays on Kanban Systems for Lean Software Development
354 Kč -
Introduction to Computation and Programming Using Python, third edition
1638 Kč -
Mastering the Art of Unreal Engine 4 - Blueprints
322 Kč -
Fundamentals of Machine Learning for Predictive Data Analytics
2240 Kč -
Kanban and Scrum - Making the Most of Both
401 Kč -
Scrum and Xp from the Trenches - 2nd Edition
506 Kč -

Back into the Storm
518 Kč -

F5 Networks Application Delivery Fundamentals Study Guide - Black and White Edition
642 Kč -

Sell Like Crazy
625 Kč -
Guide How To Install Windows Xp Sp3 For Beginner (Edition 2018)
289 Kč -
Ghidra Software Reverse Engineering for Beginners
1663 Kč -
Practical Monitoring
525 Kč -

Modern Operating Systems
1115 Kč -

Master Google Ads
328 Kč -

Internet of Things, revised and updated edition
318 Kč -
Rebooting AI
311 Kč -
101 Python Challenges with Solutions / Code Listings
556 Kč -
Debian Administrator's Handbook, Debian Jessie from Discovery to Mastery
995 Kč -

Ready-Made Visual FoxPro Applications for File Maintenance
180 Kč -

Blender - The Ultimate Guide - Volume 1
678 Kč -
International Journal for Digital Art History
511 Kč -

SCADA Security - What's broken and how to fix it
1064 Kč -

Programming Boot Sector Games
670 Kč -
Selenium Testing Tools Cookbook -
1143 Kč -
Prestashop 1.6 User Guide
891 Kč -
Getting Value Out of Agile Retrospectives - A Toolbox of Retrospective Exercises
359 Kč -
Oracle APEX Reporting Tips & Tricks
598 Kč -
Heads-Up Online Poker Excellence Guide
263 Kč -
Citrix XenDesktop & XenApp 7.7/7.8
1217 Kč -
Undisturbed Rest: a Guide to Designing the Perfect API
555 Kč -

Thinking in Promises
692 Kč -

Windows Xp Sp3 Install Guide
556 Kč -
Node .Js
660 Kč -
Coreldraw Training Guide
636 Kč -

Who Are You?
530 Kč -

Python Architecture Patterns
1034 Kč
Osobní odběr Praha, Brno a 48429 dalších
Copyright ©2008-26 nejlevnejsi-knihy.cz Všechna práva vyhrazenaSoukromíCookies

 Vrácení do měsíce
 571 999 099 (8-15.30h)
