Kód: 53879150
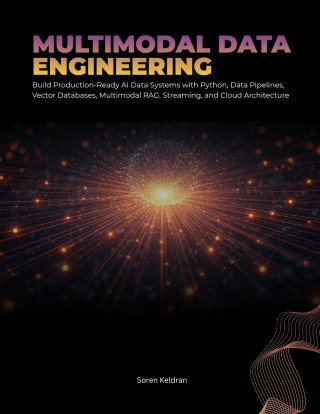
Multimodal Data Engineering
Autor Soren Keldran
AI applications are moving beyond text-but most data pipelines were never designed for what comes next.Getting a multimodal AI prototype to work is one thing. Engineering the infrastructure that keeps documents, images, audio, vid ... celý popis


- Jazyk:
 Angličtina
- Vazba: Brožovaná
- Počet stran: 208
Nakladatelství: Independently published, 2026
- Více informací o knize


Mohlo by se vám také líbit
-
Threshing Day (Wing and Claw Collection)
400 Kč -
Threshing Day (Limited Deluxe Edition)
473 Kč -
Berserk Deluxe Volume 1
879 Kč -
What Happened Yesterday
380 Kč -
White Nights
89 Kč -
Murdoku
334 Kč -
Berserk Deluxe Volume 2
941 Kč -
Court of Thorns and Roses 6
358 Kč -
Berserk Deluxe Volume 3
801 Kč -
21 Days of Fear
396 Kč -
Jojo's Bizarre Adventure: Part 7--Steel Ball Run, Vol. 8
427 Kč -
Onyx Storm (Deluxe Limited Edition) (The Empyrean, 3)
551 Kč -
Kid's Box New Generation Level 2 Activity Book with Digital Pack British English
288 Kč -
The Art of Gravity Falls
851 Kč -
Yesteryear
325 Kč -
The Courage To Be Disliked
206 Kč -
Kid's Box New Generation Level 3 Activity Book with Digital Pack British English
251 Kč -
Witch Hat Atelier: Grimoire Edition 1
755 Kč -
Dancing The Dream
482 Kč -
Magic the Gathering Reality Fracture Secret Lair Bundle english
2709 Kč -
Kid's Box New Generation Level 1 Activity Book with Digital Pack British English
251 Kč
Dárkový poukaz: Radost zaručena
- Darujte poukaz v libovolné hodnotě a my se postaráme o zbytek.
- Poukaz se vztahuje na celou naši nabídku.
- Elektronický poukaz vytisknete z e-mailu a můžete ihned darovat.
- Platnost poukazu je 12 měsíců od data vystavení.
Více informací o knize Multimodal Data Engineering
Nákupem získáte 42 bodů
 Anotace knihy

AI applications are moving beyond text-but most data pipelines were never designed for what comes next.
Getting a multimodal AI prototype to work is one thing. Engineering the infrastructure that keeps documents, images, audio, video, structured data, metadata, embeddings, and retrieved context synchronized and trustworthy in production is another.
You may already know Python, SQL, ETL, APIs, databases, or cloud fundamentals. But modern AI data engineering introduces new challenges. How do you build reliable AI data pipelines without losing provenance? Keep embeddings and vector indexes synchronized when sources change? Combine batch processing with real time data pipelines? Prevent stale or unauthorized evidence from reaching production RAG systems?
Multimodal Data Engineering gives you the architecture, engineering principles, and practical techniques to solve these problems in production.
Through one evolving Production Multimodal Data Platform, you'll learn how modern AI data architecture connects ingestion, storage, processing, metadata, representations, retrieval, streaming, governance, and operations.
Inside, you'll learn how to:
Engineer pipelines for text, PDFs, images, audio, video, and structured data
Design reliable batch, streaming, and event-driven architectures
Build object storage, lakehouse, metadata, lineage, and versioning layers
Process multimodal data with OCR, transcription, segmentation, enrichment, and quality controls
Engineer version-aware embedding pipelines and apply vector database engineering principles
Build semantic search, hybrid retrieval, metadata filtering, and reranking
Develop Kafka-based streaming with ordering, replay, backpressure, idempotency, and recovery
Engineer multimodal RAG with evidence retrieval, context assembly, provenance, freshness, and evaluation
Apply security, governance, privacy, lineage, and AI data observability
Practice AI infrastructure engineering with Docker, Kubernetes, AWS, Azure, and Google Cloud
Optimize CPU, GPU, storage, network, retrieval, and infrastructure costs
Troubleshoot stale embeddings, index drift, consumer lag, retrieval failures, bad context, OOM failures, and compound system failures
Engineer reliability, disaster recovery, CI/CD, SLOs, incident response, and capacity planning
Designed with a Beginner → Professional progression, the book is accessible to ambitious readers with basic Python or general software and data knowledge while developing the architectural reasoning required for professional systems.
Whether you're a Data Engineer, AI Engineer, ML Engineer, MLOps Engineer, Software Engineer, Cloud or Platform Engineer, or Data Scientist, you'll learn how the pieces fit together-not just how individual tools work.
This is not another book about prompting or training foundation models.
It's about engineering the data systems that make multimodal AI reliable, searchable, scalable, governable, and production-ready.
If you're ready to move beyond traditional ETL and fragile AI prototypes, get Multimodal Data Engineering and start building production-ready AI data systems.
Parametry knihy
423 Kč
- Plný název: Multimodal Data Engineering
- Podnázev: Build Production-Ready AI Data Systems with Python, Data Pipe-lines, Vector Databases, Multimodal RAG, Streaming, and Cloud Architecture
- Autor: Soren Keldran
- Jazyk: Angličtina
- Vazba: Brožovaná
- Počet stran: 208
- EAN: 9798173578624
- ID: 53879150
- Nakladatelství: Independently published
- Hmotnost: 495 g
- Rozměry: 280 × 216 × 11 mm
- Datum vydání: 12. September 2026
Osobní odběr Praha, Brno a 47879 dalších
Copyright ©2008-26 nejlevnejsi-knihy.cz Všechna práva vyhrazenaSoukromíCookies

 Vrácení do měsíce
 571 999 099 (8-15.30h)
