Kód: 51396786
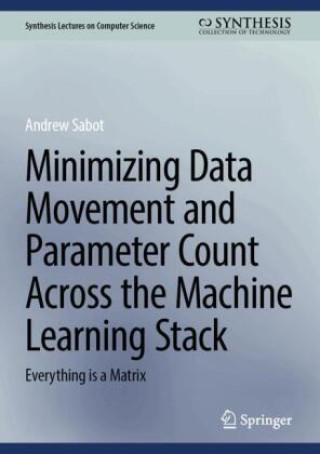
Minimizing Data Movement and Parameter Count Across the Machine Learning Stack
Autor Andrew Sabot
This book provides a focused, research-forward guide to making large AI models efficient in practice and also presents an array of novel techniques to reduce memory footprint, accelerate computation, and improve overall hardware u ... celý popis


- Jazyk:
 Angličtina
- Vazba: Pevná
- Počet stran: 165
Nakladatelství: Springer, Berlin, 2026
- Více informací o knize

1034 Kč
Dostupnost:
50 % šance Máme informaci, že by titul mohl být dostupný. Na základě vaší objednávky se ho pokusíme do 6 týdnů zajistit.
Prohledáme celý svět
Mohlo by se vám také líbit
-

Mój książę. Bridgertonowie. Tom 1. Wydawnictwo Zysk
396 Kč -

Gimson's Pronunciation of English
1819 Kč -

Tolle Tier-Silben-Geschichten mit Conni
132 Kč -

The Best Fake Book Ever: E-Flat Edition
906 Kč -

Introduction to Health Care Management
2266 Kč -

Advanced Technologies for Rechargeable Batteries
2171 Kč -

Fun Throughout All the Seasons in Nature Coloring Book
308 Kč -

CBCT in Practice: Imaging Fundamentals and Clinical Insights
1620 Kč -

Der spirituelle Weg zur Wunscherfüllung
369 Kč -

AUTHENTIC CONGA RHYTHMS REVISED
590 Kč -

History of Family Photography: Through the Photos of the Hamel and Landry Families of Rhode Island
1269 Kč -

Awesome Pit Crews
927 Kč -

The History of Italy, from the Fall of the Western Empire to the Commencement of the Wars of the French Revolution, by George Perceval, Esq, Volume 2
728 Kč -

Is Slavery Sanctioned By The Bible?
258 Kč -

ESSENTIAL ELEMENTS POP SONGS FOR TRUMPET
300 Kč -
El Correo Sino-annamita, Volume 23...
903 Kč -

Revelation Comes from Elsewhere
3553 Kč -

DAS GUTE LEBEN
221 Kč -

King John
207 Kč -

Exposition Et Histoire Des Principales Découvertes Scientifiques Modernes, Volume 1
638 Kč -

Die Arithmetik Der Quadratischen Formen, Part 1
750 Kč
Dárkový poukaz: Radost zaručena
- Darujte poukaz v libovolné hodnotě a my se postaráme o zbytek.
- Poukaz se vztahuje na celou naši nabídku.
- Elektronický poukaz vytisknete z e-mailu a můžete ihned darovat.
- Platnost poukazu je 12 měsíců od data vystavení.
Informovat o naskladnění knihy
Zadejte do formuláře e-mailovou adresu a jakmile knihu naskladníme, zašleme vám o tom zprávu. Pohlídáme vše za vás.
Více informací o knize Minimizing Data Movement and Parameter Count Across the Machine Learning Stack
Nákupem získáte 103 bodů
 Anotace knihy

This book provides a focused, research-forward guide to making large AI models efficient in practice and also presents an array of novel techniques to reduce memory footprint, accelerate computation, and improve overall hardware utilization. The author demonstrates that substantial efficiency gains can be achieved by rethinking how data is computed, stored, and compressed, with a special focus on matrices, the core computational structure underpinning both scientific computing and neural networks. Modern AI models run on huge grids of numbers (matrices/tensors), and their speed and affordability depend on how those numbers are arranged and processed on real hardware (GPUs/TPUs/CPUs). This book explains practical methods to skip unnecessary work (structured sparsity), move data efficiently (gather/scatter), and shrink models without losing accuracy (block distillation) so that AI systems can use less memory, less time, and less energy without sacrificing quality. In addition, the book shows how to turn algorithmic ideas into hardware-aware speedups on GPUs/TPUs. Readers will learn when sparsity pays off, how to schedule irregular workloads, and how to recover accuracy in compressed models. Case studies illustrate end-to-end design choices, evaluation, and pitfalls. The result is a coherent perspective that bridges theory, compilers/run times, and real-world deployment.
Parametry knihy
Zařazení knihy Knihy v angličtině Computing & information technology Computer science Artificial intelligence
1034 Kč
- Plný název: Minimizing Data Movement and Parameter Count Across the Machine Learning Stack
- Podnázev: Everything is a Matrix
- Autor: Andrew Sabot
- Jazyk: Angličtina
- Vazba: Pevná
- Počet stran: 165
- EAN: 9783032230997
- ID: 51396786
- Nakladatelství: Springer, Berlin
- Hmotnost: 341 g
- Rozměry: 240 × 168 mm
- Datum vydání: 16. May 2026
Oblíbené z jiného soudku
-
More Everything Forever
358 Kč -
Sciences of the Artificial
1137 Kč -
Designing Human-Centric AI Experiences
1034 Kč -
Neuronal Dynamics
1688 Kč -
Data Mining
1155 Kč -
Advances in Financial Machine Learning
941 Kč -
Dive into Deep Learning
722 Kč -
Book of Why
276 Kč -
Real-Time C++
1154 Kč -
Linear Algebra and Optimization for Machine Learning
1269 Kč -
Why Greatness Cannot Be Planned
536 Kč -
Lambda Calculus. Its Syntax and Semantics
682 Kč -
Practical Time Series Analysis
1268 Kč -
Natural Language Processing in Action
1441 Kč -
Tiny ML
801 Kč -
Superminds
279 Kč -
Graph Neural Networks: Foundations, Frontiers, and Applications
1901 Kč -
Genetic Algorithms
1154 Kč -
Google Gemini - Einstieg und Praxis - Texte, Bilder, Videos mit KI generieren
410 Kč -
Deep Learning
1843 Kč -
Deep Learning
2132 Kč -
On Intelligence
358 Kč -
Artificial Intelligence Basics
723 Kč -
Pattern Recognition and Machine Learning
1729 Kč -
Pattern Recognition and Machine Learning
2205 Kč -
Words and Rules
381 Kč -
Computer Vision
1384 Kč -
Python Machine Learning -
1034 Kč -
Introduction to Information Theory, Symbols, Signals and Noise
443 Kč -
Eye Tracking Methodology
1545 Kč -
AI for Games Developers
645 Kč -
High-Dimensional Probability
1831 Kč -
Dancing with Qubits
2210 Kč -
Large Language Models: A Deep Dive
1384 Kč -
Artificial Intelligence and Games
1384 Kč -
Deep Reinforcement Learning
4707 Kč -
Handbook of Computational Linguistics and Natural Language Processing
1117 Kč -
Intelligent Techniques for Data Science
1729 Kč -
Natural Language Processing: Python and NLTK
2019 Kč -
Intelligence Analysis as Discovery of Evidence, Hypotheses, and Arguments
1510 Kč -
Genetic Programming
1182 Kč -
Prompting kurz & gut
408 Kč -
Anomaly Detection Principles and Algorithms
1753 Kč -
Fundamentals of Computational Swarm Intelligence
3484 Kč -
Reinforcement Learning
2545 Kč -
Machine Learning Design Patterns
1124 Kč -
Deep Learning
344 Kč -
Python Machine Learning
1206 Kč -
We have been harmonised
297 Kč
Osobní odběr Praha, Brno a 47805 dalších
Copyright ©2008-26 nejlevnejsi-knihy.cz Všechna práva vyhrazenaSoukromíCookies

 Vrácení do měsíce
 571 999 099 (8-15.30h)
